When CSV to JSON extra columns are missing from your output, the cause is usually a data row that has more cells than the header row. With Header row enabled, the CSV to JSON converter on this site uses the first record as object keys and, according to the tool page, drops any cells beyond the number of headers without warning. The most common trigger is an unquoted comma inside a value. It splits one value into two cells and pushes every later value one position to the right.
The input here is pasted CSV text and the output is a JSON array of objects, so the repair belongs in the source CSV. Below I show a three-header example, a quote-aware field-count check you can run before converting, the RFC 4180 quoting repairs, and a way to compare the result afterward. The dropping behavior comes from the tool’s documentation, not from my own benchmark.
Table of Contents
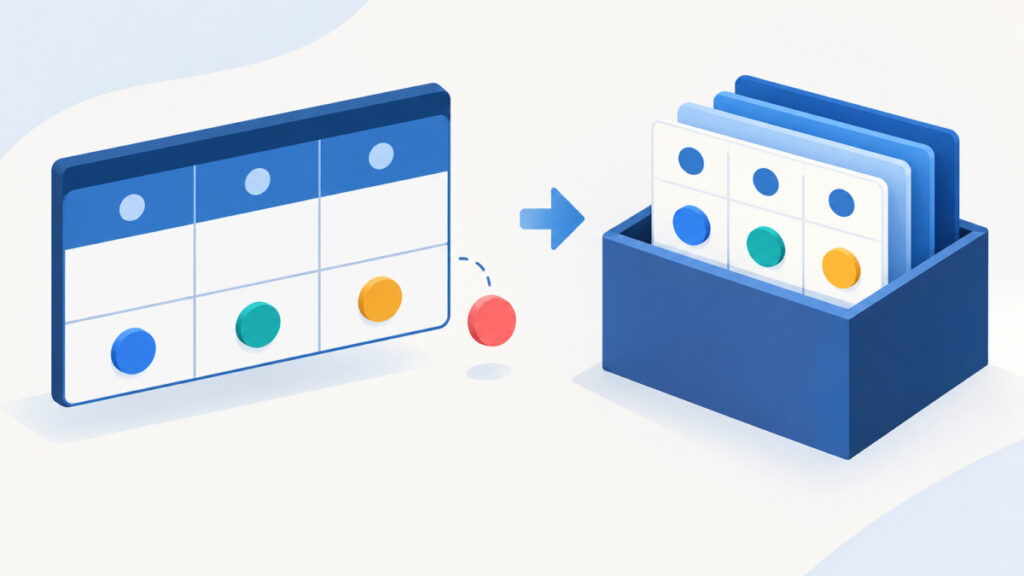
Three headers, four cells: a minimal before and after
Start with a header that names three fields and a data row that, once parsed with a comma delimiter, has four. The input is plain CSV text and the expected output is one JSON object per data row.
product,description,status
P1,blue, large,ready
A quote-aware parser reads the data record as four cells: P1, blue, large and ready. The header supplies only three keys, so the fourth cell has nowhere to go. With Header row enabled, the converter drops it, and the result looks like this (shown compactly for clarity, since the site offers output formatting choices):
[{"product":"P1","description":"blue","status":"large"}]Two things went wrong at once. The status key is present but holds large, which is a fragment of the description, and the real status ready is gone. The last column did not disappear. The last value lost its key. That difference matters: a missing JSON key usually suggests an empty cell, while a missing CSV value here points to a row whose shape no longer matches its header.
Now quote the field that contains the comma, so the comma becomes data instead of a separator:
product,description,status
P1,"blue, large",ready
[{"product":"P1","description":"blue, large","status":"ready"}]Every header now has exactly one value, and nothing is dropped. I used P1 as the identifier so the example does not depend on the Auto types setting.
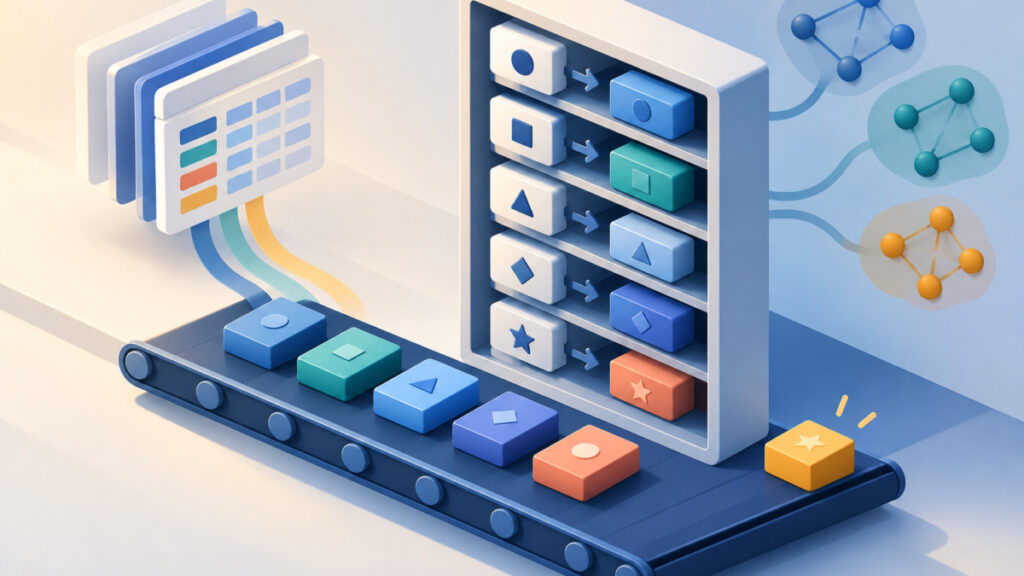
CSV to JSON extra columns missing: how header mapping drops cells
The mapping is positional. With Header row enabled, the tool reads the first record as the list of keys, then pairs each later cell with the key at the same position. A cell in position four has no fourth key to pair with, so, as the tool page documents, it is dropped without warning. I am describing this site’s documented behavior only. JSON itself does not require a converter to discard overflow cells, and Python’s csv.DictReader shows the alternative: its documentation says extra fields are kept in a list under the restkey name instead of being thrown away.
Not every extra cell is equally harmful. A stray trailing comma, such as P2,red,ready,, adds an empty fourth cell. The converter drops that empty cell, which hides the malformed row but loses no data. A populated last value vanishing points to a different cause: an unquoted comma inside a value. It splits one value into two cells and shifts everything after it, so later values land under the wrong keys before the final one is dropped.
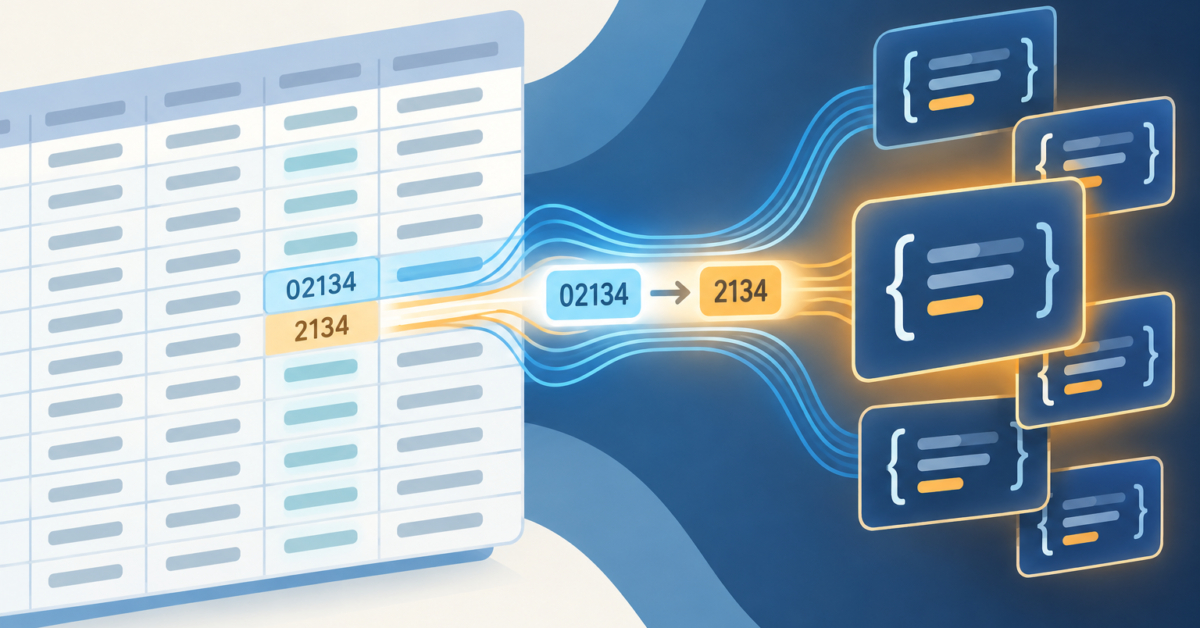
Turning Header row off gives arrays instead of objects. That keeps cells by position, but it does not repair malformed CSV, and the rows still disagree about how many cells they hold. The tool also documents Auto types and delimiter auto-detection as separate causes of surprising output, such as a ZIP code losing a leading zero or a delimiter being guessed differently than you intended. Neither one fixes an unequal field count, so rule the field count out first. For the wider conversion workflow and options, the complete CSV to JSON guide covers the basics.
Count fields to catch CSV to JSON extra columns missing errors
The check has three parts. Confirm the delimiter, parse the header and every data record with a quote-aware CSV reader, and flag each record whose field count differs from the header count. Do not use string.split(',') or count text lines. Both miscount valid CSV, because a quoted field may contain commas and line breaks.
import csv

with open('input.csv', newline='', encoding='utf-8') as f:
    reader = csv.reader(f, delimiter=',')
    header = next(reader)
    for record_number, row in enumerate(reader, start=2):
        if len(row) != len(header):
            print(record_number, len(header), len(row))
Each printed line shows the record number, the header field count and the field count of the offending record. For the broken example above, the output is 2 3 4. The header counts as record 1, so the first data record is 2. Call this a record number, not necessarily a physical line number, because quoted fields can contain line breaks and one record can span several lines.
Fix each flagged record, then run the script again until it prints nothing. If your file uses semicolons or tabs, change the delimiter argument to match, and select the same delimiter in the converter. Comma-based fixes make no sense on a semicolon file.
If you would rather see the overflow than count it, Python’s DictReader can keep it under a name you choose:
import csv

with open('input.csv', newline='', encoding='utf-8') as f:
    reader = csv.DictReader(f, restkey='_extra')
    for row in reader:
        if '_extra' in row:
            print(row['product'], row['_extra'])
For the broken row this prints P1 ['ready'], which shows exactly which value had no header. Both snippets only read the file, so they are safe to run on a copy of your data.
Repair the source CSV with RFC 4180 quoting rules
RFC 4180, published in October 2005, is an informational description of CSV rather than a strict standard that every parser follows, but its quoting rules are the safest common ground. It says headers and records should have matching field counts, the last field should not be followed by a comma, fields containing commas or line breaks should be enclosed in double quotes, and a literal double quote inside a quoted field is written as two double quotes. Apply those rules to the flagged records:
- Embedded comma: wrap the whole field in double quotes, as in
"blue, large". - Stray trailing delimiter: remove the final comma when the last field is genuinely empty and the header does not expect it.
- Embedded double quote: double it inside a quoted field, as in
"12"" pipe, blue". - Line break inside a value: keep it, but enclose the field in double quotes.
Before deleting any comma, decide whether it is data or a separator. In blue, large the comma belongs to the description, so quoting is right. If instead a column is genuinely missing from that row, deleting or quoting would hide the real problem, and you should fix the row’s values. Here is a small file that uses all the rules above:
product,description,status
P1,"blue, large",ready
P2,red,ready
P3,"12"" pipe, blue",ready
The third record parses as P3, 12" pipe, blue and ready, which is three fields. The field-count script from the previous section should now print nothing.
If the CSV comes from a script that joins strings with commas, fix the producer to use a real CSV writer instead of patching files by hand. For a second look at quoting from the export side, see the CSV quoting check in the JSON-to-CSV one-row guide.
Reconvert and compare every expected key and value
With the repaired CSV, paste it into the converter, pick the delimiter that matches the file, keep Header row enabled, and convert. Then compare, because a clean-looking result proves little by itself. Check that the number of objects equals the number of data records, that every object has every header as a key, and that the last column holds what the source holds, especially in rows you repaired.
A short script catches shape problems and shifted values. It assumes jsonText holds the converter output as a string, and the allowed status values are fictitious:
const expectedKeys = ['product', 'description', 'status'];
const allowedStatus = new Set(['ready', 'shipped']);
const rows = JSON.parse(jsonText);

rows.forEach((row, index) => {
  const hasAllKeys = expectedKeys.every((key) => key in row);
  const statusOk = allowedStatus.has(row.status);
  if (!hasAllKeys || !statusOk) {
    console.log('Check object', index, row);
  }
});
The value check is what would have flagged large sitting under status. Syntax tools do not do that job. The JSON Validator confirms the text parses with the browser’s JSON.parse, which is useful for ruling out a broken paste, but valid JSON can still contain shifted values. If you want a second angle, run the JSON back through the JSON to CSV converter and compare the rows with your source. That round trip can reveal differences, though it is not a formal proof of equivalence.
If the result still looks odd after the field counts match, look at the separate settings. Auto types can change how values such as ZIP codes are typed, and delimiter auto-detection can guess differently from what you intended. Choosing the delimiter explicitly removes one variable.
Frequently asked questions
Does the CSV to JSON converter warn me when it drops cells?
According to the tool page, no. With Header row enabled, data cells beyond the number of headers are dropped without a warning. That is why checking field counts before conversion matters, since the output still looks like valid JSON.
Why does the last key hold the wrong value instead of being empty?
Cells are paired with headers by position. An unquoted comma splits one value into two cells, so every later value shifts one key to the right. The last key receives a fragment of the previous value, and the true final value has no key left.
Can I turn off Header row to keep every cell?
Turning Header row off produces arrays instead of objects, so cells keep their positions. It does not repair malformed CSV, though, and the rows will still disagree on how many cells they contain. Fix the quoting in the source file first.
Why shouldn't I count commas or lines to check a CSV file?
Valid CSV can contain commas and line breaks inside double-quoted fields. Splitting on commas or counting text lines will miscount those files. A quote-aware reader, such as Python’s csv module, counts fields the way the format defines them.
Is a trailing comma at the end of a row a problem?
RFC 4180 says the last field in a record should not be followed by a comma. A stray one adds an empty extra cell, which this converter drops with headers enabled. It usually hides a malformed row but does not by itself explain a populated value disappearing.
What if my file uses semicolons or tabs instead of commas?
Select the matching delimiter in the converter and set the same delimiter in your field-count check. Applying comma-based fixes to a semicolon file can introduce new errors. Delimiter auto-detection exists, but choosing the delimiter yourself removes the guesswork.
Do all CSV to JSON converters discard extra cells?
No. This article describes only the documented behavior of this site’s tool. Other software can behave differently. Python’s DictReader, for example, keeps surplus fields in a list under its restkey name instead of silently dropping them.
Next steps
If CSV to JSON extra columns are missing from your output, treat it as a field-count problem in the source, not a lost column. The documented behavior is that cells beyond the header count are dropped, and an unquoted comma is the usual reason a populated value ends up beyond that count. Run the quote-aware count, quote embedded commas and double embedded quotes following RFC 4180, then reconvert and check values as well as keys. As a next step, take one file that has gone wrong, run the field-count script on a copy, fix the first flagged record, and convert again.
Related tools and resources on HTML Editor Online:
- CSV to JSON
- How to Convert CSV to JSON: The Complete Guide for Developers
- Why Is My JSON-to-CSV Export One Row Instead of One Row per Record?
- JSON Validator