You paste {"id":12345678901234567} into a validator, get a success message, and the normalized copy shows 12345678901234568. Nothing was rejected, yet the last digit moved. This is the moment a JSON validator changes large integer ID values without reporting any error, and it confuses analysts and developers because valid sounds like unchanged.
The short answer is that the text was valid JSON, but a JavaScript-based tool turned the unquoted number into a binary64 Number, which cannot hold every integer that large. In this article I use the JSON Validator to compare the input with the normalized copy, explain the JSON.parse precision limit and show how to keep identifiers as strings. The prerequisite is basic familiarity with JSON strings and numbers. All sample data is synthetic, and the numeric results are the documented JavaScript behavior, not a recorded run of the site.
Table of Contents
Why a JSON validator changes large integer ID values
Start with a synthetic record. The ID has 17 digits and is written as a JSON number, without quotes.
{
  "id": 12345678901234567,
  "status": "active"
}
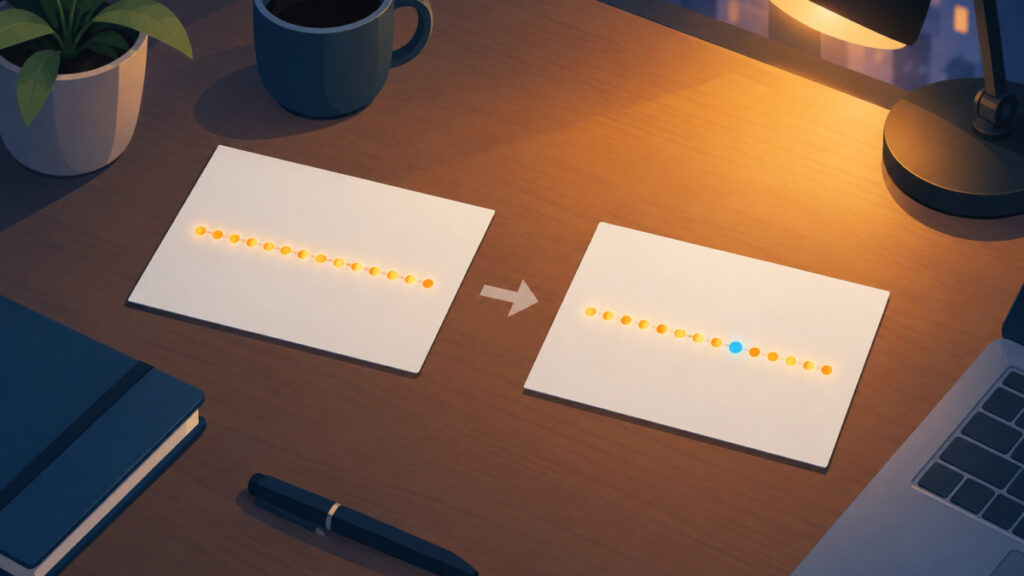
After parsing and re-serializing with two-space indentation, the normalized copy is expected to look like this:
{
  "id": 12345678901234568,
  "status": "active"
}
Only the final digit differs, which is exactly why the problem is easy to miss. The keys, the structure and the record count all look right. A lookup by that ID would fail, or worse, match a different record. If the number is a database key, an order reference or a customer identifier, a one-digit shift breaks identity.
Two separate things happened. First, the tool parsed the text, and that succeeded because the text follows the JSON grammar. Second, the tool wrote the parsed value back out, and the value it wrote was the nearest number JavaScript could store, not the one you typed. The loss occurs during parsing. Serializing the resulting Number only exposes it.
Valid JSON does not promise exact numbers in every parser
JSON is a text format. RFC 8259 describes a number as digits with an optional fraction and exponent, and it sets no maximum digit count. The same document warns that implementations differ in the range and precision they accept. It also says software that reads numbers as IEEE 754 binary64 values agrees exactly only for integers from -9,007,199,254,740,991 through 9,007,199,254,740,991 (see the RFC 8259 information page).
So valid answers a syntax question: does this text follow the grammar? It does not answer a storage question: can the receiver keep this number exactly? A JavaScript Number is a binary64 value, and MDN documents that integers beyond Number.MAX_SAFE_INTEGER may not be represented exactly. That makes the trouble a property of the receiving Number, not of JSON. A parser that reads the same text into an arbitrary-precision or decimal type could keep every digit, which is why I avoid saying JSON has a digit limit.
A second trap is the reviver, the optional second argument of JSON.parse. MDN notes that it normally runs after the value has been parsed, so numeric precision may already be gone by the time your function sees it. A reviver is therefore not a dependable place to rescue a large integer.
In short, three separate questions get blurred together: is the syntax valid, does the receiving type hold the value exactly, and does the receiving contract expect a number or a string. A green validation result answers only the first.
Compare input and normalized output in the JSON Validator
Here is a repeatable way to check an ID with the site’s validator.
- Keep the original text somewhere else first, such as the export file or the raw API response body. You need an untouched copy to compare against.
- Open the JSON Validator and paste the original text into Input JSON.
- Click Validate.
- Read the result, then compare the ID in Normalized Output with your original, character by character, before you copy or download anything.
The page describes its check as the browser’s JSON.parse followed by a re-serialized copy that can be indented or sorted by key. It does not check a JSON Schema. Success therefore means the text parsed. It does not certify that the output keeps every input digit, and key sorting or indentation do nothing to protect numbers.
The same caution applies to neighboring tools. The JSON Formatter documents a parse-then-stringify path, so pretty-printing is not a lossless workaround. The JSON Editor documents that its Format and Minify actions rebuild parsed data and may round large numbers. Its syntax validation is likewise a JSON.parse check with no schema validation.
I would not reach for JSON Repair either. Repair targets malformed syntax, such as trailing commas or single quotes. Your input is already well-formed, and no repair step can restore digits that rounding removed. For general habits around readable output, these tips for formatting JSON are a useful companion, but they do not change how numbers are stored.
Why 17 digits is not the real rule
The dividing line is 9,007,199,254,740,991, exposed in JavaScript as Number.MAX_SAFE_INTEGER. Above it, the gap between neighboring representable Numbers grows. Between 2^53 (9,007,199,254,740,992) and 2^54 (18,014,398,509,481,984), only every second integer can be stored. The example ID sits in that band. 12345678901234567 is odd, so it lies exactly halfway between 12345678901234566 and 12345678901234568, and IEEE 754 round-to-nearest, ties-to-even selects the latter.
You can reproduce the behavior in any JavaScript console. This is an illustrative snippet, and the comments show the expected results from documented behavior:
const original = '{"id":12345678901234567}';
const parsed = JSON.parse(original);

console.log(parsed.id);                  // 12345678901234568
console.log(JSON.stringify(parsed));     // {"id":12345678901234568}
console.log(Number.isSafeInteger(parsed.id)); // false
If you want to run it in the browser, the JavaScript Editor executes code and shows synchronous console output.
Digit count alone is an unreliable alarm. Consider these two cases:
JSON.parse('{"id":12345678901234568}').id; // 12345678901234568, unchanged
JSON.parse('{"id":9007199254740993}').id;  // 9007199254740992, a 16-digit change
An even 17-digit value in that band can survive, while a 16-digit value just above the safe limit can change. Not every 17-digit ID rounds, and surviving one test proves nothing about the next record.
The helper Number.isSafeInteger is worth using as a flag. MDN describes a safe integer as one that can be represented exactly and whose representation does not come from rounding some other integer to fit. Here, both 12345678901234567 and 12345678901234569 round to 12345678901234568, so it is not safe. The flag cannot recover anything, though. After rounding, the value is an ordinary-looking number, and nothing in it records the digits you started with.
Keep the ID as a string when the contract allows it
If the receiving API or schema accepts a string, quote the identifier from the earliest point at which the original digits still exist. Compare this version with the first example:
{
  "id": "12345678901234567",
  "status": "active"
}
After validation, the normalized copy should show the same digits, because a JSON string is a sequence of characters, not a quantity. The quotes change the value’s type, not just its display. An ID identifies a record and is rarely added or averaged, so text is a natural fit. It also keeps leading zeros and avoids treating the digits as a number.
Do not simply wrap quotes around the rounded output. Quoting 12345678901234568 gives you a well-typed string containing the wrong ID. The fix has to happen before parsing, in the exporter, the database driver or the API layer that first sees the digits.
Check the contract before changing anything. In JSON Schema, string and integer are different types, so a field declared as an integer will reject the quoted form. Here is a sample contract, clearly hypothetical, that expects a 17-digit string:
{
  "type": "object",
  "properties": {
    "id": { "type": "string", "pattern": "^[0-9]{17}$" },
    "status": { "type": "string" }
  },
  "required": ["id"]
}
The site’s validator cannot tell you which form the recipient wants, because it does not check a schema. If the contract demands an integer, you need to coordinate a contract change or agree on a lossless integer path through every stage of the pipeline.
Inside JavaScript application code, BigInt can hold the exact value, but JSON.stringify throws a TypeError for a BigInt by default, as MDN documents. A replacer can convert it to a string, which is the same contract decision in disguise:
const record = { id: 12345678901234567n, status: 'active' };
const text = JSON.stringify(record, (key, value) =>
  typeof value === 'bigint' ? value.toString() : value
);
console.log(text); // {"id":"12345678901234567","status":"active"}
The n suffix makes the literal a BigInt, so the digits are exact. The output is a quoted string, so anyone consuming it must accept a string ID.
Checklist for finding where the JSON validator changes a large integer ID
When digits differ, the goal is to find the earliest step where they changed. Work through this list in order.
- Get the rawest copy. Use the original file or response body as text, before any tool has opened it. Compare the ID character by character, or compare the length of the digit sequence.
- Check upstream steps. An exporter or spreadsheet may have altered the value before it ever reached the validator. If the data passed through a conversion, inspect that output too. The guide on how to convert CSV to JSON is useful background for those steps.
- Validate and compare. Paste the raw text into the validator and check the ID in Normalized Output against your untouched copy.
- Confirm in code. Parse the raw text in a console and call
Number.isSafeIntegeron the result. A false value means the parsed Number cannot be trusted as an identifier. - Read your parser’s documentation. Find out whether your API client or library reads JSON numbers into Numbers. That is where the loss enters a pipeline.
- Change to a string at the source. Quote the ID where the digits are still exact, confirm the recipient accepts a string, then validate again and compare.
One more edge case: sometimes the digits in the original are already wrong. If the raw response body itself lacks the correct ID, no downstream fix can restore it, and the problem sits with whoever produced the data. For a broader tour of editing habits, the online JSON editor guide covers the workflow around the JSON tools.
Treat the comparison as a habit rather than a one-off debugging step. Whenever an identifier passes through a tool that parses, keep the original and compare it with what comes back.
Frequently asked questions
Is a 17-digit integer valid JSON?
Yes. RFC 8259 defines number syntax without a maximum digit count, so a 17-digit integer is valid text. What can go wrong is the receiving software. A JavaScript-based parser stores it as a binary64 Number, which cannot represent every integer that large exactly.
Do all 17-digit IDs change after validation?
No. Above 9,007,199,254,740,991, a Number can store only certain integers, and in the range around 12 quadrillion that means even values. An even ID such as 12345678901234568 survives, while the odd 12345678901234567 rounds. Digit count alone is not the rule.
Can a JSON.parse reviver restore the original digits?
Not reliably. MDN notes that a reviver normally runs after parsing, so precision may already be lost when it sees the value. To keep exact digits, store the ID as a string in the source data or use a parser designed to preserve large integers.
Should identifiers always be strings in JSON?
Often, but check the contract first. An ID is used for identity rather than arithmetic, so text is a natural fit. If the receiving API or schema declares an integer, a quoted string will be rejected, and the change must be agreed with the recipient.
Can I add quotes around the rounded value in the normalized output?
No. That produces a string containing the wrong digits, such as 12345678901234568 instead of 12345678901234567. The quotes must be added at the earliest point where the original digits are still available, then you re-validate and compare.
Does the JSON Validator check a schema or catch this precision change?
It uses the browser’s JSON.parse and shows a re-serialized normalized copy. It does not check a JSON Schema, and it does not warn about rounding. Compare the ID in Normalized Output with your original text yourself.
Does BigInt solve the problem in JavaScript?
It helps inside application code because a BigInt keeps exact digits. However, JSON.stringify throws a TypeError for BigInt by default. You must convert it, for example to a string with a replacer, which again means the receiver has to accept a string.
Next steps
When a JSON validator changes large integer ID values, the input was not invalid and the tool did not break. A JavaScript Number simply cannot store every integer above 9,007,199,254,740,991 exactly, and the rounded digits appear in the normalized copy because parsing already happened. Keep identifiers as strings whenever the receiving schema allows, create the string before the digits pass through a Number, and confirm the contract, because a schema treats a string and an integer as different types. Save the original, compare it with the normalized output every time, and treat a green validation as a syntax result only.
Related tools and resources on HTML Editor Online:
Sources and further reading
- https://www.rfc-editor.org/info/rfc8259/
- https://developer.mozilla.org/en-US/docs/Web/JavaScript/Reference/Global_Objects/JSON/parse
- https://developer.mozilla.org/en-US/docs/Web/JavaScript/Reference/Errors/BigInt_not_serializable
- https://developer.mozilla.org/en-US/docs/Web/JavaScript/Reference/Global_Objects/Number/isSafeInteger
- https://json-schema.org/understanding-json-schema/reference/numeric?highlight=number
- https://developer.mozilla.org/en-US/docs/Web/JavaScript/Reference/Global_Objects/Number
- https://json-schema.org/understanding-json-schema/reference/string
- JSON Validator – Free Online JSON Validator | HTML Editor Online

